Disclaimer: The opinions expressed in this article are my own and do not represent the views of Google. This content is based solely on publicly available information.
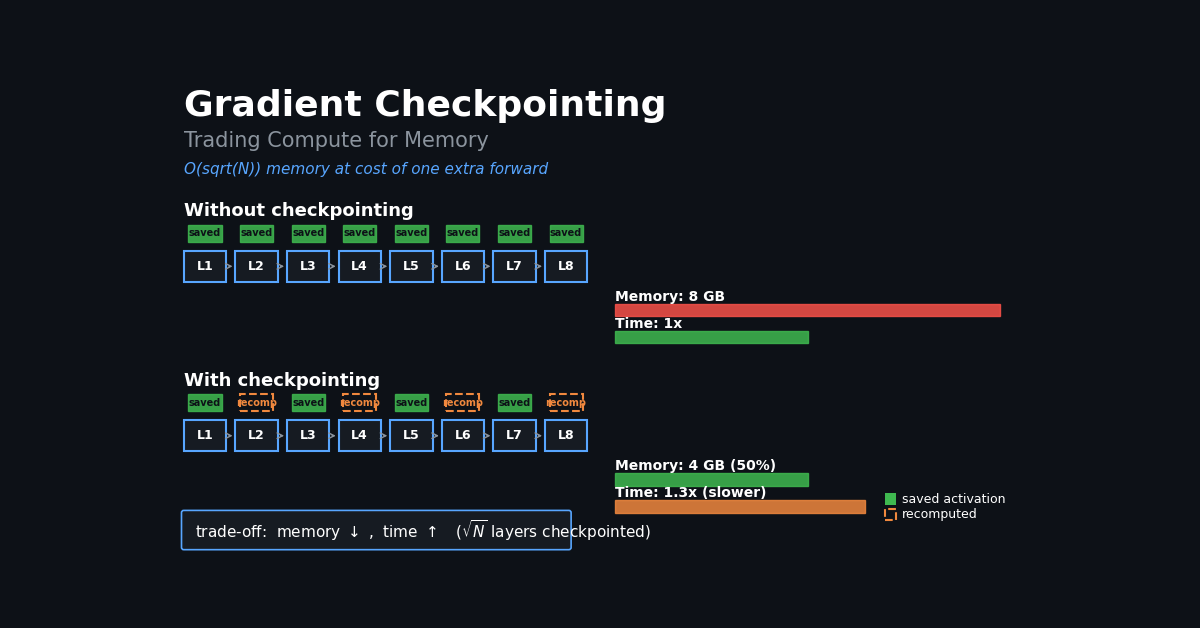
Gradient checkpointing re-runs parts of the forward pass during backprop instead of keeping all intermediate activation tensors in memory — trading FLOPs for VRAM. Training a 32-layer transformer with d_model=4096, d_ffn=16384, batch size 4, and sequence length 2048 requires 54 GB of activation memory alone — before parameters (12 GB) or Adam moments (48 GB). Total: 114 GB. An A100 80GB cannot hold it. Gradient checkpointing solves this by discarding most activation tensors during the forward pass and recomputing them on demand during the backward pass. The cost: checkpointing every 4 layers saves ~30% memory at the price of one extra forward pass during the backward step — usually the best operating point.
Why Backprop Needs to Store Activations
To understand why gradient checkpointing exists, you need to see what backpropagation demands from memory.
During the forward pass, each layer computes an output from its input. During the backward pass, the chain rule requires multiplying the incoming gradient by the local Jacobian of each layer. For nearly every layer type used in transformers — linear projections, softmax, layer norm, GELU — the Jacobian depends on the activations that were produced during the forward pass.
Consider a single linear layer y = Wx. The output gradient with respect to W is ∂L/∂W = (∂L/∂y)ᵀ x, which requires the input x. The gradient with respect to x is ∂L/∂x = Wᵀ (∂L/∂y), which requires the weight W (already in memory). For a softmax with output p, the backward step computes ∂L/∂z = p ⊙ (∂L/∂p) − pᵀ(∂L/∂p)p, which requires p — the post-softmax attention weights.
The rule is general: to backprop through a layer, you must have the layer’s output (or input) from the forward pass. With N layers, standard backprop therefore keeps all N layers of activations alive from the moment the forward pass ends until backward finishes processing each layer in reverse order. For large models, this is the dominant memory cost.
Gradient checkpointing breaks this requirement. Instead of keeping all activations, it keeps only a subset — the “checkpoints” — and recomputes intermediate activations on demand. The tradeoff is extra computation; the reward is sub-linear memory in the number of layers.
What Activations Cost
Each transformer layer stores activations for the backward pass. For a forward pass at batch B, sequence length S, hidden dimension D, FFN dimension D_ffn, and H attention heads, the dominant tensors are:
- Q, K, V projections:
3 × B × S × D - Attention weights (softmax output):
B × H × S × S← grows quadratically inS - Attention output:
B × S × D - FFN intermediate (post-activation):
B × S × D_ffn - FFN output:
B × S × D - Residual activations:
2 × B × S × D(pre-attention and pre-FFN)
import numpy as np

GB = 1024**3


def activation_memory_per_layer(batch: int, seq_len: int, d_model: int,
                                 d_ffn: int, n_heads: int, dtype_bytes: int = 2) -> dict:
    """Bytes of activations saved per transformer layer for the backward pass."""
    qkv = 3 * batch * seq_len * d_model
    attn_weights = batch * n_heads * seq_len * seq_len      # [B, H, S, S]
    attn_out = batch * seq_len * d_model
    ffn_intermediate = batch * seq_len * d_ffn
    ffn_out = batch * seq_len * d_model
    residuals = 2 * batch * seq_len * d_model

    total = qkv + attn_weights + attn_out + ffn_intermediate + ffn_out + residuals
    return {
        "qkv_gb": qkv * dtype_bytes / GB,
        "attn_weights_gb": attn_weights * dtype_bytes / GB,
        "ffn_gb": (ffn_intermediate + ffn_out) * dtype_bytes / GB,
        "residuals_gb": residuals * dtype_bytes / GB,
        "total_per_layer_gb": total * dtype_bytes / GB,
    }


def total_training_memory(n_layers: int, batch: int, seq_len: int, d_model: int,
                           d_ffn: int, n_heads: int, dtype_bytes: int = 2) -> dict:
    """Params + Adam (FP32 m + v) + all-layer activations."""
    n_params = n_layers * (4 * d_model * d_model + 2 * d_model * d_ffn)
    params_gb = n_params * dtype_bytes / GB
    optimizer_gb = n_params * 8 / GB           # 8 bytes/param: FP32 m + v
    per = activation_memory_per_layer(batch, seq_len, d_model, d_ffn, n_heads, dtype_bytes)
    activations_gb = n_layers * per["total_per_layer_gb"]
    return {
        "params_gb": params_gb,
        "optimizer_gb": optimizer_gb,
        "activations_gb": activations_gb,
        "total_gb": params_gb + optimizer_gb + activations_gb,
        "n_params_b": n_params / 1e9,
    }


config = {"d_model": 4096, "d_ffn": 16384, "n_heads": 32, "dtype_bytes": 2}

print("=== Activation Memory Per Layer (d_model=4096, d_ffn=16384) ===")
for batch, seq_len in [(1, 2048), (4, 2048), (4, 4096), (8, 2048)]:
    mem = activation_memory_per_layer(batch, seq_len, **config)
    print(f"\n  Batch={batch}, Seq={seq_len}:")
    print(f"    Q/K/V tensors:     {mem['qkv_gb']:.2f} GB")
    print(f"    Attention weights: {mem['attn_weights_gb']:.2f} GB  <- O(S^2), quadratic in seq")
    print(f"    FFN tensors:       {mem['ffn_gb']:.2f} GB")
    print(f"    Residuals:         {mem['residuals_gb']:.2f} GB")
    print(f"    Total/layer:       {mem['total_per_layer_gb']:.2f} GB")
    print(f"    x 32 layers:       {32 * mem['total_per_layer_gb']:.2f} GB")

print()
print("=== Total Training Memory (BF16, 32-layer 6.4B model, batch=4, seq=2048) ===")
total = total_training_memory(n_layers=32, batch=4, seq_len=2048, **config)
print(f"  Parameters:     {total['params_gb']:.2f} GB  ({total['n_params_b']:.2f}B params)")
print(f"  Optimizer:      {total['optimizer_gb']:.2f} GB  (Adam FP32 m + v)")
print(f"  Activations:    {total['activations_gb']:.2f} GB  (32 layers stored)")
print(f"  Total:          {total['total_gb']:.2f} GB")
print(f"  A100 80GB:      {'FITS' if total['total_gb'] <= 80 else 'DOES NOT FIT'}")
Output:
=== Activation Memory Per Layer (d_model=4096, d_ffn=16384) ===

  Batch=1, Seq=2048:
    Q/K/V tensors:     0.05 GB
    Attention weights: 0.25 GB  <- O(S^2), quadratic in seq
    FFN tensors:       0.08 GB
    Residuals:         0.03 GB
    Total/layer:       0.42 GB
    x 32 layers:       13.50 GB

  Batch=4, Seq=2048:
    Q/K/V tensors:     0.19 GB
    Attention weights: 1.00 GB  <- O(S^2), quadratic in seq
    FFN tensors:       0.31 GB
    Residuals:         0.12 GB
    Total/layer:       1.69 GB
    x 32 layers:       54.00 GB

  Batch=4, Seq=4096:
    Q/K/V tensors:     0.38 GB
    Attention weights: 4.00 GB  <- O(S^2), quadratic in seq
    FFN tensors:       0.62 GB
    Residuals:         0.25 GB
    Total/layer:       5.38 GB
    x 32 layers:       172.00 GB

  Batch=8, Seq=2048:
    Q/K/V tensors:     0.38 GB
    Attention weights: 2.00 GB  <- O(S^2), quadratic in seq
    FFN tensors:       0.62 GB
    Residuals:         0.25 GB
    Total/layer:       3.38 GB
    x 32 layers:       108.00 GB

=== Total Training Memory (BF16, 32-layer 6.4B model, batch=4, seq=2048) ===
  Parameters:     12.00 GB  (6.44B params)
  Optimizer:      48.00 GB  (Adam FP32 m + v)
  Activations:    54.00 GB  (32 layers stored)
  Total:          114.00 GB
  A100 80GB:      DOES NOT FIT
At batch=4, sequence=2048, just storing activations costs 54 GB — close to the entire A100 budget by itself. Doubling the sequence to 4096 explodes activation memory to 172 GB on the same 32-layer model: the quadratic B × H × S × S attention-weights tensor is the worst offender, growing from 1.00 GB to 4.00 GB per layer.
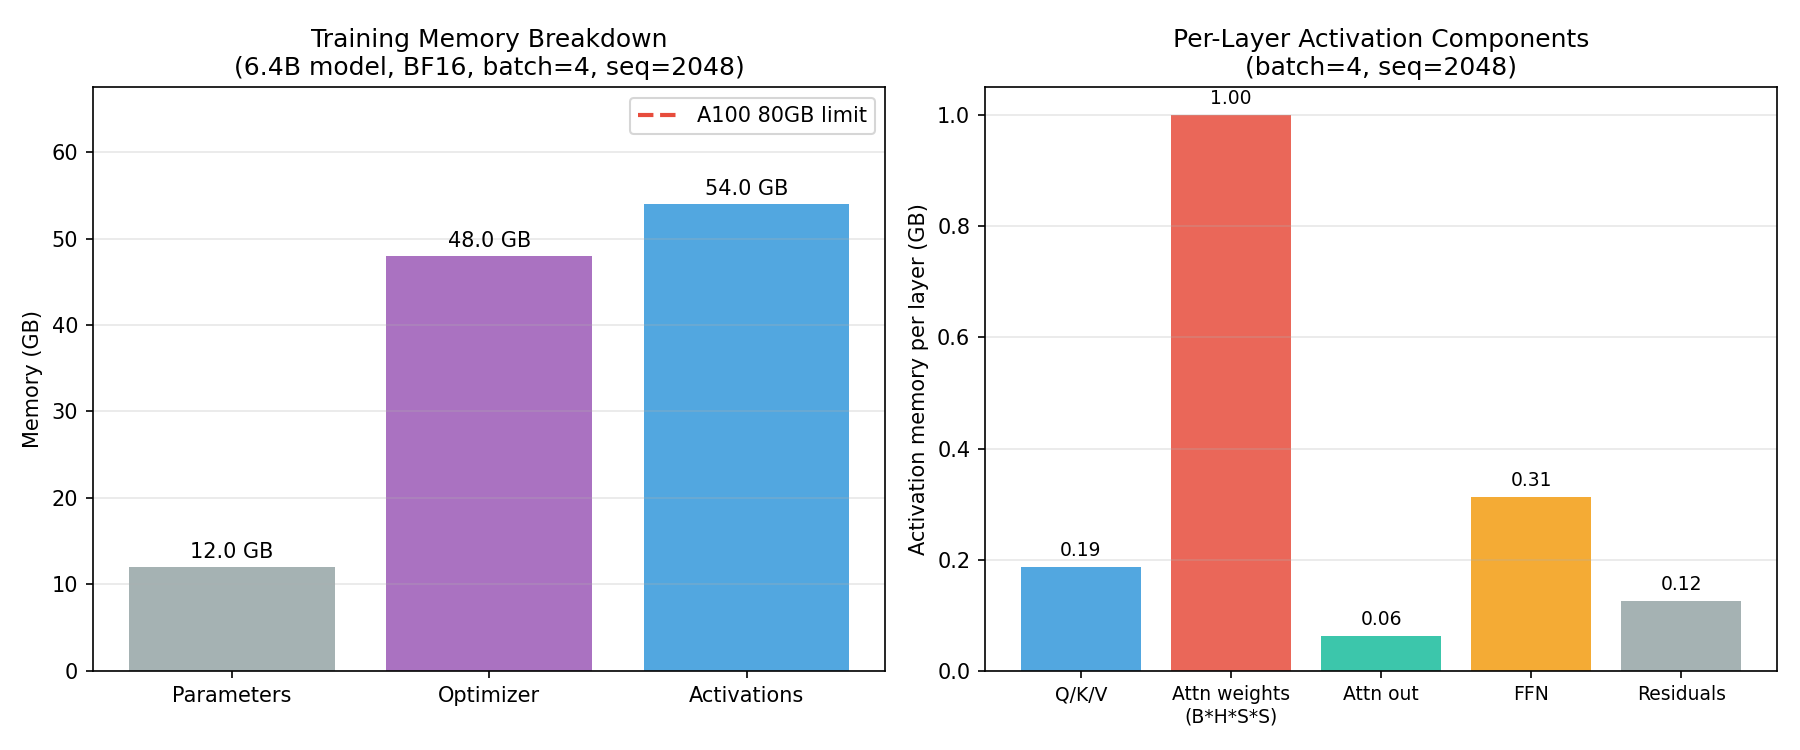
Figure 1: Left — training memory split for the 6.4B model. Right — per-layer activation components at batch=4, seq=2048.
The left panel makes the headline problem visual: at batch=4, seq=2048, the three big blocks are parameters (12 GB), Adam moments (48 GB), and activations (54 GB), with activations alone the largest single bucket. The right panel breaks down a single layer’s activations — the attention-weights tensor at 1.00 GB per layer is the largest single tensor and the only one whose footprint grows with S².
How Gradient Checkpointing Works
Without checkpointing, every layer’s activations stay in memory for the entire backward pass. With checkpointing, only activations at chosen “boundary” layers are kept; the activations between boundaries are discarded and recomputed during the backward pass when needed.
A 32-layer model with checkpoint_every=4 keeps activations at layers 4, 8, 12, …, 32 (eight boundaries). During backward, the runtime re-runs forward on the four layers in the current segment to materialize their activations, gradients flow back through that segment, then memory is freed before processing the next segment.
The standard accounting:
- Memory:
(N/K) × act_per_layerfor boundaries +K × act_per_layerfor the currently-live segment. This is(N/K + K)layer-units total, minimized atK = √N— the sublinear-memory result from Chen et al. (2016), Training Deep Nets with Sublinear Memory Cost, which introduced the technique. - Extra forward FLOPs during backward:
(N − N/K) / N = (K − 1)/Kof one forward pass. ForK=4andN=32: 24 of 32 layers get recomputed, i.e. 75% of one extra forward. - As a fraction of a full step (forward + 2× backward ≈ 3 forward passes), that 75% becomes ~25% extra compute.
def simulate_memory_and_flops(n_layers: int, checkpoint_every: int,
                               activation_gb_per_layer: float) -> dict:
    """Memory and recompute cost at a given checkpoint interval.

    Stored activations = boundaries + one live segment in flight:
        (N/K) + K layer-units, minimized at K = sqrt(N).
    """
    n_checkpoints = n_layers // checkpoint_every
    if checkpoint_every == 1:
        activation_mem_gb = n_layers * activation_gb_per_layer
    else:
        activation_mem_gb = (n_checkpoints + checkpoint_every) * activation_gb_per_layer

    layers_recomputed = n_layers - n_checkpoints
    extra_forward_pct = layers_recomputed / n_layers * 100         # % of one forward pass
    extra_step_pct = extra_forward_pct / 3.0                       # % of full step

    return {
        "checkpoint_every": checkpoint_every,
        "activation_gb": activation_mem_gb,
        "extra_forward_pct": extra_forward_pct,
        "extra_step_pct": extra_step_pct,
    }


n_layers = 32
act_per_layer = 1.6875     # 54.00 GB / 32 layers (batch=4, seq=2048)
fixed_gb = 12.00 + 48.00   # params + Adam moments

print("=== Gradient Checkpointing Tradeoff ===")
print(f"Fixed memory (params + optimizer): {fixed_gb:.2f} GB")
print(f"Activation per layer:              {act_per_layer:.4f} GB")
print()
print(f"{'Ckpt every':>11} {'Act GB':>8} {'Total GB':>10} {'Saved':>8} "
      f"{'+Fwd %':>8} {'+Step %':>8}")
print("-" * 60)

base = simulate_memory_and_flops(n_layers, 1, act_per_layer)
base_total = fixed_gb + base["activation_gb"]
for ck in [1, 2, 4, 8, 16, 32]:
    r = simulate_memory_and_flops(n_layers, ck, act_per_layer)
    total = fixed_gb + r["activation_gb"]
    saved_pct = (base_total - total) / base_total * 100
    tag = "  <- store all" if ck == 1 else (
          "  <- full recompute" if ck == 32 else "")
    print(f"{ck:>11} {r['activation_gb']:>7.2f} {total:>9.2f}  "
          f"{saved_pct:>6.1f}%  {r['extra_forward_pct']:>6.1f}%  "
          f"{r['extra_step_pct']:>6.1f}%{tag}")
Output:
=== Gradient Checkpointing Tradeoff ===
Fixed memory (params + optimizer): 60.00 GB
Activation per layer:              1.6875 GB

 Ckpt every   Act GB   Total GB    Saved   +Fwd %  +Step %
------------------------------------------------------------
          1   54.00    114.00     0.0%     0.0%     0.0%  <- store all
          2   30.38     90.38    20.7%    50.0%    16.7%
          4   20.25     80.25    29.6%    75.0%    25.0%
          8   20.25     80.25    29.6%    87.5%    29.2%
         16   30.38     90.38    20.7%    93.8%    31.2%
         32   55.69    115.69    -1.5%    96.9%    32.3%  <- full recompute
Two non-obvious observations fall out of this table. First, every 4 and every 8 give identical memory because (N/K + K) is symmetric around √N ≈ 5.66; the optimal interval lives between them. Second, every 32 (full recompute) is actually worse than every 1 here, because keeping a single 32-layer segment live during recompute consumes more memory than the boundaries it saves. The sweet spot is not “checkpoint everything”; it is K ≈ √N.
Max Batch on a Single A100
Memory savings only matter if they unlock a larger batch (and therefore higher GPU utilization). The next sweep fixes the GPU at A100-80GB and asks: for each checkpoint interval, what is the biggest batch that still fits?
def max_batch_for_ckpt(n_layers: int, ck_every: int, act_per_layer_b1: float,
                        fixed_gb: float, gpu_gb: float = 80.0) -> int:
    """Binary search over batch size to find the largest that fits in gpu_gb."""
    max_b = 0
    for b in range(1, 65):
        r = simulate_memory_and_flops(n_layers, ck_every, act_per_layer_b1 * b)
        if fixed_gb + r["activation_gb"] <= gpu_gb:
            max_b = b
        else:
            break
    return max_b


n_layers = 32
fixed_gb = 60.0
act_per_layer_b1 = 1.6875 / 4   # activations scale linearly with batch

print("=== Max Batch on A100 80GB ===")
print(f"{'Ckpt every':>11} {'Max batch':>10}")
print("-" * 25)
for ck in [1, 2, 4, 8, 16, 32]:
    mb = max_batch_for_ckpt(n_layers, ck, act_per_layer_b1, fixed_gb)
    print(f"{ck:>11} {mb:>10}")
Output:
=== Max Batch on A100 80GB ===
 Ckpt every   Max batch
-------------------------
          1           1
          2           2
          4           3
          8           3
         16           2
         32           1
Without checkpointing the model only fits at batch=1. Checkpointing every 4 (or 8) layers triples the achievable batch to 3 — the largest of any interval — while still keeping the model under 80 GB.
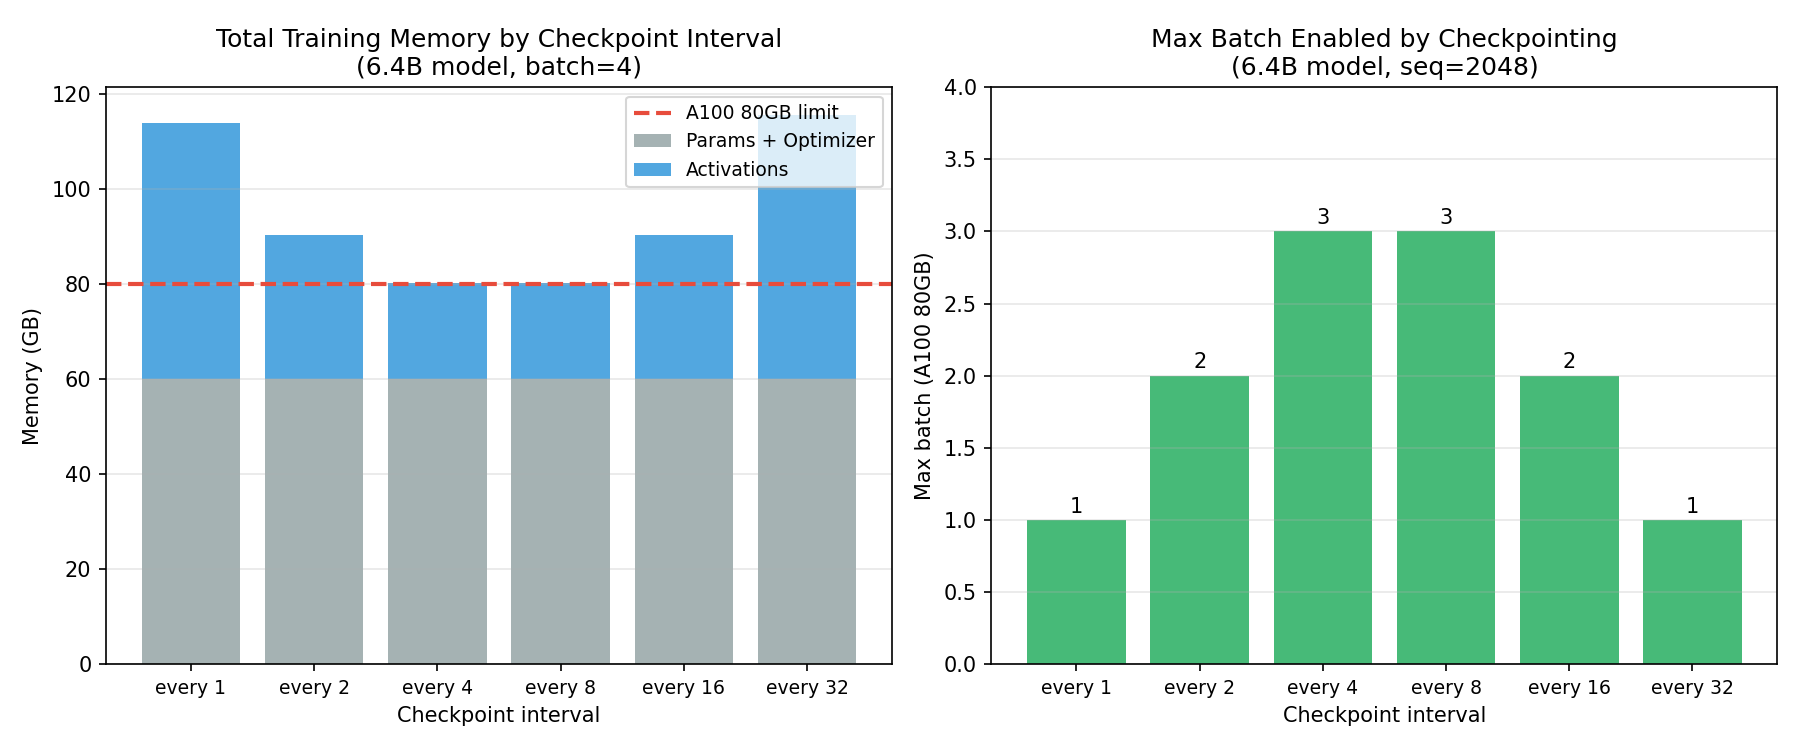
Figure 2: Left — total training memory at each checkpoint interval. Right — max batch on A100 80GB by interval.
The left panel shows what the saving-percentage column hides: every 4 and every 8 bring the memory bar to the edge of the 80 GB line (80.25 GB at batch=4, just over; batch=3 fits cleanly), and dropping the batch by one is enough to fit. The right panel confirms that the gain in batch is concentrated at those same intervals — coarser checkpointing (every 16, every 32) actually loses batch capacity because the live segment grows again.
The Memory–Compute Frontier
Tabulating memory saved against the extra forward pass exposes a clean Pareto frontier: the best checkpoint interval is the one that maximizes memory saved per unit of recompute, while still fitting in VRAM.
def frontier(n_layers: int, act_per_layer: float, fixed_gb: float,
             gpu_gb: float = 80.0):
    base = simulate_memory_and_flops(n_layers, 1, act_per_layer)
    base_total = fixed_gb + base["activation_gb"]

    print(f"{'Ckpt every':>11} {'Total GB':>10} {'Saved':>8} "
          f"{'+Fwd %':>8} {'GB / +%':>9} {'Fits 80GB':>11}")
    print("-" * 60)
    for ck in [1, 2, 4, 8, 16, 32]:
        r = simulate_memory_and_flops(n_layers, ck, act_per_layer)
        total = fixed_gb + r["activation_gb"]
        saved = (base_total - total) / base_total * 100
        eff = saved / max(r["extra_forward_pct"], 0.001)
        eff_str = "infinite" if r["extra_forward_pct"] == 0 else f"{eff:.2f}"
        fits = "YES" if total <= gpu_gb else "NO"
        print(f"{ck:>11} {total:>9.2f}  {saved:>6.1f}%  "
              f"{r['extra_forward_pct']:>6.1f}%  {eff_str:>9}  {fits:>10}")


frontier(n_layers=32, act_per_layer=1.6875, fixed_gb=60.0)
Output:
 Ckpt every   Total GB    Saved   +Fwd %   GB / +%   Fits 80GB
------------------------------------------------------------
          1    114.00     0.0%     0.0%   infinite          NO
          2     90.38    20.7%    50.0%       0.41          NO
          4     80.25    29.6%    75.0%       0.39          NO
          8     80.25    29.6%    87.5%       0.34          NO
         16     90.38    20.7%    93.8%       0.22          NO
         32    115.69    -1.5%    96.9%      -0.02          NO
All rows show NO at batch=4 because 80.25 GB slightly exceeds the 80 GB limit — the previous section showed that dropping to batch=3 clears the ceiling. Among the intervals near the optimum, every 4 is the lower-overhead winner — same memory as every 8 (both 80.25 GB) but 12.5 percentage points less recompute. Coarser is not better than every 4: once K > √N the live segment dominates and you pay more compute for less memory.
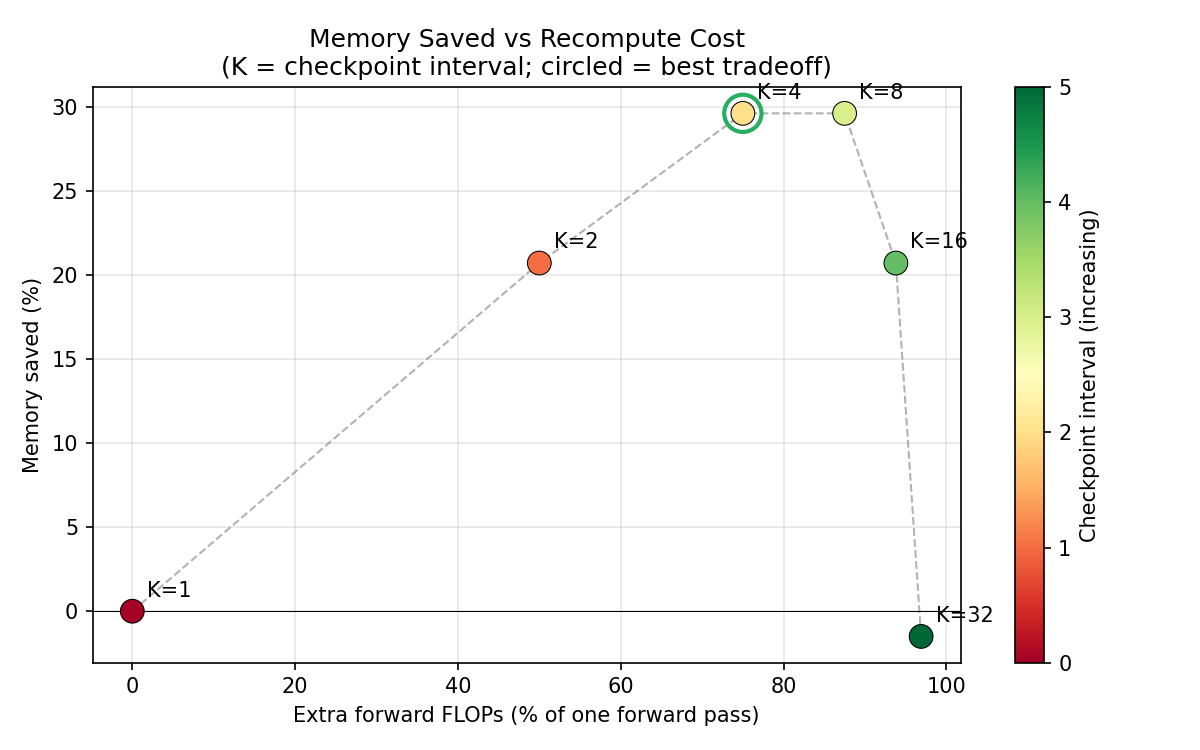
Figure 3: Memory saved versus extra forward FLOPs for each checkpoint interval; K=4 is the circled best tradeoff at batch=3 (it does not fit at batch=4 — see the frontier table).
The non-monotone shape is the central insight: the curve bends back to the right after K=8, because both every 16 and every 32 are worse than every 4 on every axis. The frontier is the segment K=1 → K=4; anything past √N is strictly dominated.
Throughput Impact
Memory savings only help if they translate into faster training. Below, “throughput” is the number of samples processed per normalized step at the max viable batch, debited by the recompute overhead.
def throughput_at_max_batch(n_layers: int, act_per_layer_b1: float,
                             fixed_gb: float, gpu_gb: float = 80.0):
    print(f"{'Ckpt every':>11} {'Max batch':>10} {'+Step %':>9} {'Tput':>8}")
    print("-" * 42)
    for ck in [1, 2, 4, 8, 16, 32]:
        max_b = 0
        for b in range(1, 65):
            r = simulate_memory_and_flops(n_layers, ck, act_per_layer_b1 * b)
            if fixed_gb + r["activation_gb"] <= gpu_gb:
                max_b = b
            else:
                break
        r = simulate_memory_and_flops(n_layers, ck, act_per_layer_b1 * max(max_b, 1))
        step_overhead = r["extra_step_pct"] / 100
        tput = max_b / (1 + step_overhead) if max_b > 0 else 0.0
        print(f"{ck:>11} {max_b:>10} {r['extra_step_pct']:>8.1f}%  {tput:>7.2f}")


throughput_at_max_batch(n_layers=32, act_per_layer_b1=1.6875 / 4, fixed_gb=60.0)
Output:
 Ckpt every  Max batch   +Step %     Tput
------------------------------------------
          1          1      0.0%     1.00
          2          2     16.7%     1.71
          4          3     25.0%     2.40
          8          3     29.2%     2.32
         16          2     31.2%     1.52
         32          1     32.3%     0.76
Even though every 4 adds 25% to step time, the 3× batch makes it ~2.4× faster end-to-end than the no-checkpointing baseline at batch=1. The simple lesson: never benchmark recompute overhead in isolation — what matters is samples per second at the largest batch the choice unlocks.
Practical Guidelines
The analysis collapses into a decision rule: pick the smallest checkpoint interval (least recompute) that fits in VRAM. The function below does this for an arbitrary model and GPU.
import numpy as np

GB = 1024**3


def activation_memory_per_layer(batch: int, seq_len: int, d_model: int,
                                 d_ffn: int, n_heads: int, dtype_bytes: int = 2) -> float:
    total = (3 * batch * seq_len * d_model
             + batch * n_heads * seq_len * seq_len
             + batch * seq_len * d_model
             + batch * seq_len * d_ffn
             + batch * seq_len * d_model
             + 2 * batch * seq_len * d_model)
    return total * dtype_bytes / GB


def recommend_checkpointing(params_b: float, gpu_gb: float, batch: int,
                              seq_len: int, n_layers: int, d_model: int,
                              d_ffn: int, n_heads: int) -> dict:
    act = activation_memory_per_layer(batch, seq_len, d_model, d_ffn, n_heads)
    n_params = params_b * 1e9
    fixed_gb = n_params * 2 / GB + n_params * 8 / GB

    for ck in [1, 2, 4, 8, 16, n_layers]:
        n_ck = n_layers // ck
        seg_factor = n_layers if ck == 1 else (n_ck + ck)
        total = fixed_gb + seg_factor * act
        if total <= gpu_gb:
            recomputed = n_layers - n_ck
            return {
                "fits": True,
                "checkpoint_every": ck,
                "total_gb": total,
                "extra_forward_pct": recomputed / n_layers * 100,
            }
    return {"fits": False}


scenarios = [
    ("6.4B on A100-80GB, batch=4, seq=2048",
     6.4, 80, 4, 2048, 32, 4096, 16384, 32),
    ("6.4B on A100-80GB, batch=2, seq=2048",
     6.4, 80, 2, 2048, 32, 4096, 16384, 32),
    ("3.1B on A100-80GB, batch=8, seq=2048",
     3.1, 80, 8, 2048, 32, 3072, 12288, 24),
    ("6.4B on A100-80GB, batch=2, seq=4096",
     6.4, 80, 2, 4096, 32, 4096, 16384, 32),
    ("13B on A100-80GB, batch=2, seq=2048",
     13.0, 80, 2, 2048, 40, 5120, 20480, 40),
]
print("=== Checkpointing Recommendations ===")
for label, *args in scenarios:
    rec = recommend_checkpointing(*args)
    if not rec["fits"]:
        print(f"  {label}:")
        print(f"    -> OOM even with full recompute; shard optimizer or reduce batch")
    else:
        print(f"  {label}:")
        print(f"    -> Checkpoint every {rec['checkpoint_every']} layers  "
              f"({rec['total_gb']:.1f} GB total, +{rec['extra_forward_pct']:.1f}% forward FLOPs)")
Output:
=== Checkpointing Recommendations ===
  6.4B on A100-80GB, batch=4, seq=2048:
    -> Checkpoint every 4 layers  (79.9 GB total, +75.0% forward FLOPs)
  6.4B on A100-80GB, batch=2, seq=2048:
    -> Checkpoint every 2 layers  (74.8 GB total, +50.0% forward FLOPs)
  3.1B on A100-80GB, batch=8, seq=2048:
    -> Checkpoint every 2 layers  (74.4 GB total, +50.0% forward FLOPs)
  6.4B on A100-80GB, batch=2, seq=4096:
    -> OOM even with full recompute; shard optimizer or reduce batch
  13B on A100-80GB, batch=2, seq=2048:
    -> OOM even with full recompute; shard optimizer or reduce batch
The recommendation is monotone in batch and sequence length: smaller batches and shorter sequences let you pick a smaller K (less recompute). Past a point — 13B parameters on a single 80GB card, or 4K sequences at non-trivial batch — even full recompute is not enough, and the only remaining knobs are optimizer sharding (ZeRO-1/FSDP), tensor parallelism, or FlashAttention to flatten the O(S²) attention-weights cost.
Summary
| Question | Answer |
|---|---|
| Why checkpointing? | Activations dominate training memory: 54 GB for a 6.4B model at batch=4, seq=2048 |
| What is discarded | All layer activations except at checkpoint boundaries; recomputed on demand during backward |
| Memory model | (N/K + K) × act_per_layer, minimized at K = √N |
| Recompute cost | (K − 1)/K of one forward pass per training step (≈ 25% extra step time at K=4, N=32) |
| Best interval | K ≈ √N: every 4 layers for a 32-layer model |
Don’t checkpoint coarser than √N | The live recompute segment grows and erases the saving |
| Sequence scaling | Attention weights are O(S²) per layer; for long sequences, pair checkpointing with FlashAttention |
Rule of thumb: start at K ≈ √N. If still OOM, shard the optimizer state (ZeRO-1/FSDP) before checkpointing more aggressively — wider intervals only help up to √N, after which they hurt both memory and compute.